The Extractor
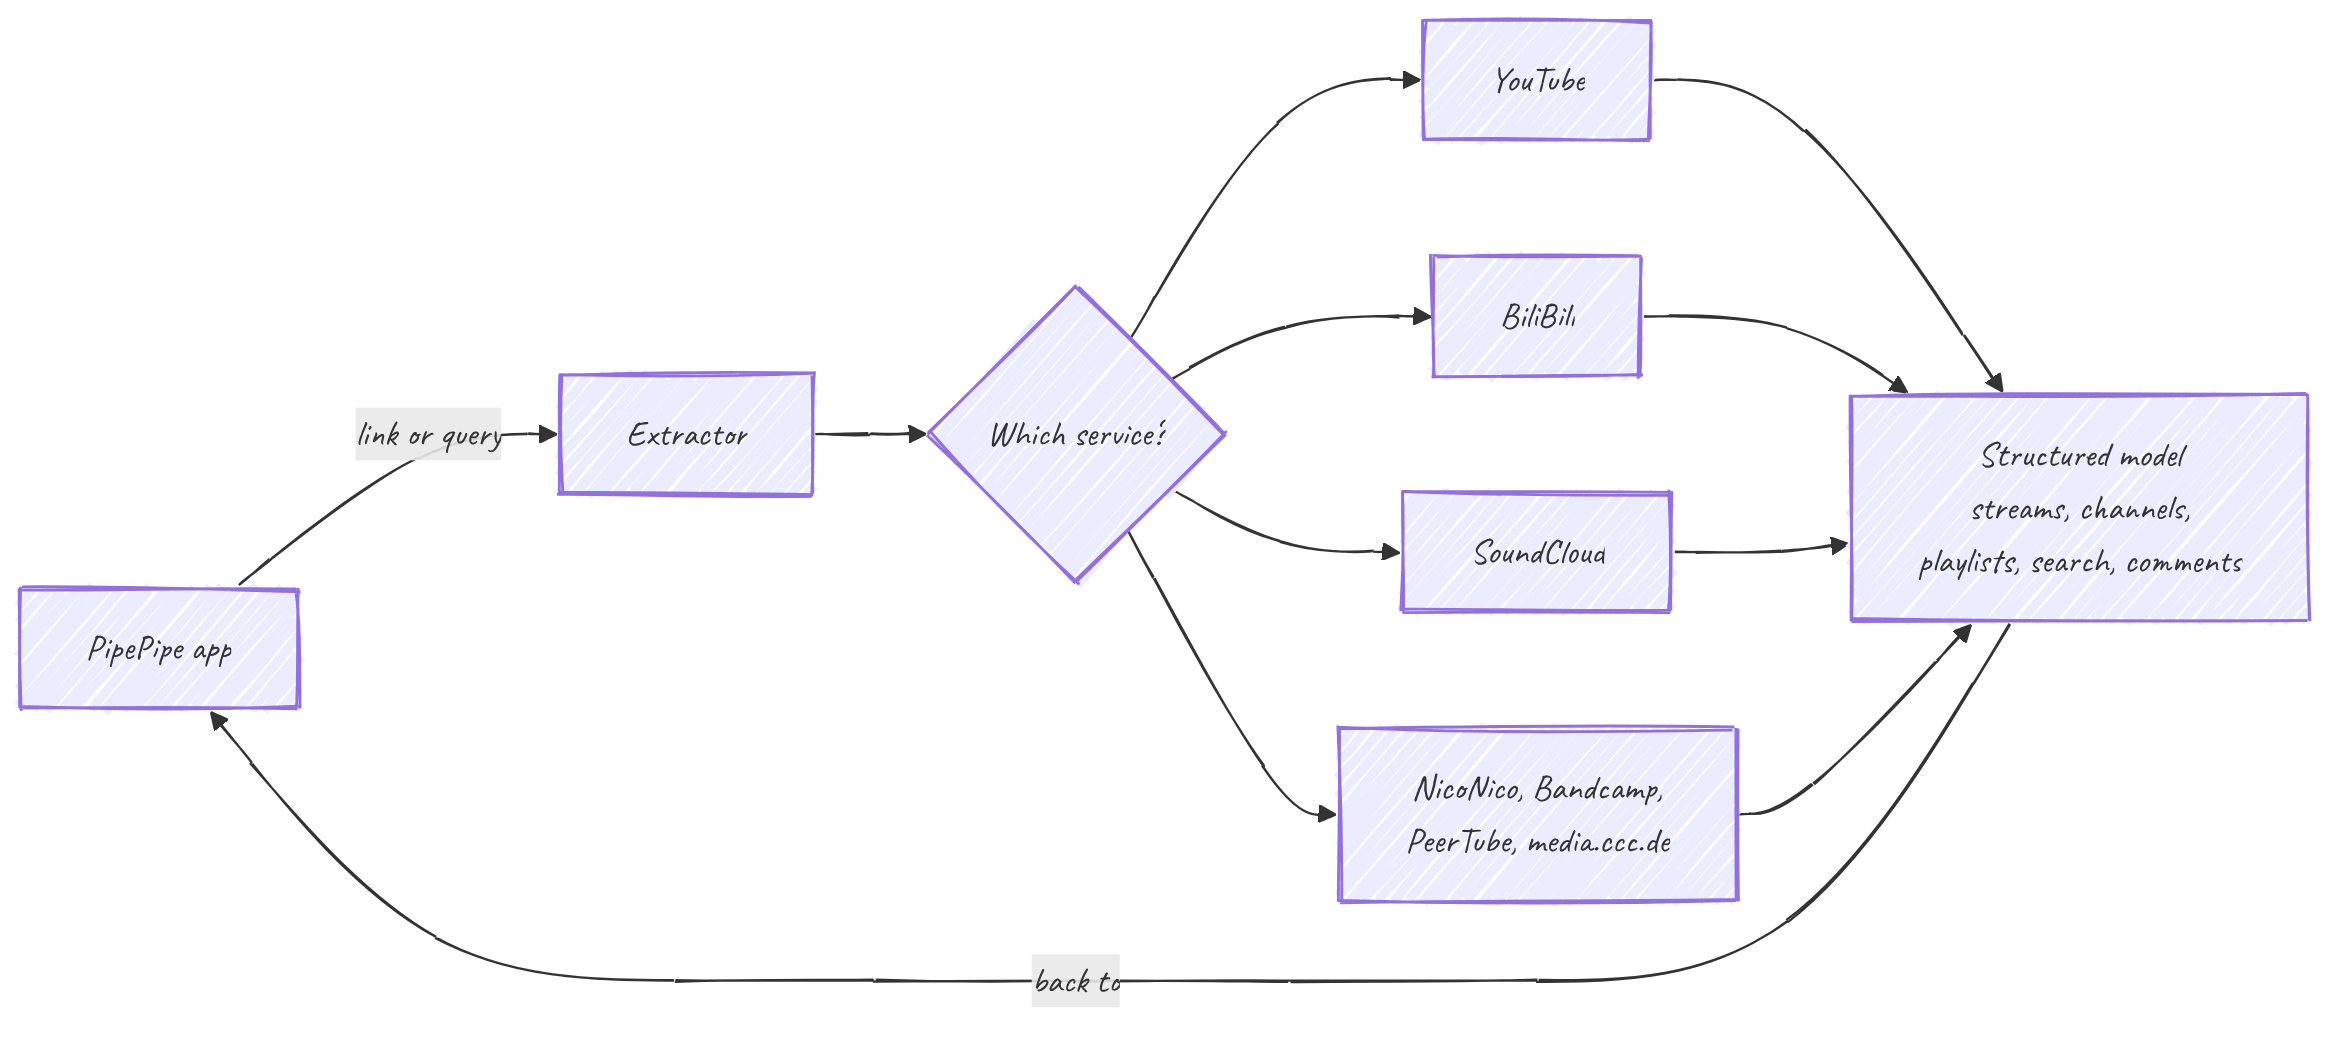
The Android app and the extractor have separate jobs. The extractor is a standalone Java library that handles service-specific requests, parsing, and structured results: a video with its streams, a channel with its tabs, a playlist, a page of results, or a comment thread. The app supplies the network downloader and turns those results into screens, playback, and downloads.
It started as a fork of NewPipe's extractor, and the package path (org.schabi.newpipe.extractor) still shows it. That is worth stating once and then setting aside: the two codebases have diverged heavily. Services, abstractions, parsing, and behavior differ enough that NewPipe's documentation, issues, and patches rarely map cleanly onto PipePipe. Treat this as its own codebase, not a NewPipe mirror.
PipePipe's app repository integrates specific revisions of both components when it builds an app release. Follow the PipePipe app repository to see which revisions are included in a particular build, and use the live PipePipeExtractor source when reading the library itself. YouTube's extraction path is covered in Inside YouTube; SABR spans both the extractor and Android player, as described in the SABR guide.
The module is self-contained. It builds and tests on its own, without the Android app around it, against a small Downloader abstraction the host supplies.
Services covered today: YouTube, BiliBili, NicoNico, SoundCloud, Bandcamp, PeerTube, and media.ccc.de. Each is a separate implementation of one shared set of interfaces. That is the design: the rest of the code is written against the abstractions, never against a specific site. "Get the streams of this video" is the same call whether the backend is YouTube or SoundCloud; the per-service mess stays behind the interface.
That uniformity is also why the extractor is the fragile layer. The interfaces are stable; the sites behind them are not. A service can change its layout or API overnight and break extraction for that one service while the others keep working. Most of the work here is keeping each service in step with a site that never agreed to be parsed, and YouTube is the loudest example.
What this section covers
A developer-level tour of how the extractor is built, for contributors reading the code.
- Architecture: the
StreamingServiceentry point and the family of extractors hanging off it. - Extraction flow: what happens from a URL to a finished
StreamInfo. - Streams and delivery: how media is described once extraction is done, the streams, formats, and
DeliveryMethods the player consumes. This is also where it connects to SABR.